MajorCheckout
ProductIncidents
Drafted for you. Published by a human.
A metric that stays unhealthy drafts the incident. You read it, publish it and post the updates. Subscribers hear each step.
An incident, played as a timeline. 14:00: Healthy. Readings under 1%. 14:02: Threshold crossed. One reading over is not an outage yet. 14:05: Metric flips unhealthy. It stayed over for the 3 minute confirmation time. 14:05: Draft created. Owners get an email to review it. The status page does not change. 14:08: Published. An owner publishes from the console. Subscribers and Slack hear about it. 14:19: Update posted. Identified. Subscribers and Slack get the update. 14:41: Resolved. A closing message resolves it. One email, one channel post.
One incident, start to finish
Checkout5xx rateHealthy. Readings under 1%.
14:00:00
Alert channel (Slack here) Email
Console, Updates
Your teamNothing open
No open incidents or maintenance. Post an update when something needs telling.
Status page
PublicAcme status
Incidents
Last 24 hours
No incidents in the last 24 hours.
The console row and the status page are the product's own components, played from sample data.
Auto-drafts
Ready to publish. Never public until it is.
Set a policy per metric. When it turns unhealthy, the incident is drafted with the context already written.
The policy
At the flip, or after it holds.
Draft as soon as the metric flips unhealthy, or only once it has stayed unhealthy for 1 to 60 minutes. The flip itself already waits out the metric's confirmation time, so one bad reading drafts nothing.
Auto-drafting is on Pro and up. Incidents by hand work on every plan.
What the draft carries
The context, already written.
- Titlenames the metric
- Severityfrom your policy
- Affected servicesfrom the metric's SLOs
- Readingagainst its threshold
- Nearest changesuggested by timing
Owners are emailed
Review from the inbox.
Org owners get the draft with signed Publish and Dismiss links, valid for 24 hours.
One outage, one incident
No pile of duplicates.
If the same service already has an unresolved incident from the last hour, the new reading is added to it instead.
Untouched drafts
They expire.
A draft nobody publishes is removed after 24 hours. The metric stays quiet for an hour after a draft, a dismissal or an expiry.
Never public
Not until someone publishes.
The status page, incident history, feeds, embeds and the public API only show published incidents.
Console / Updates / Auto-drafts
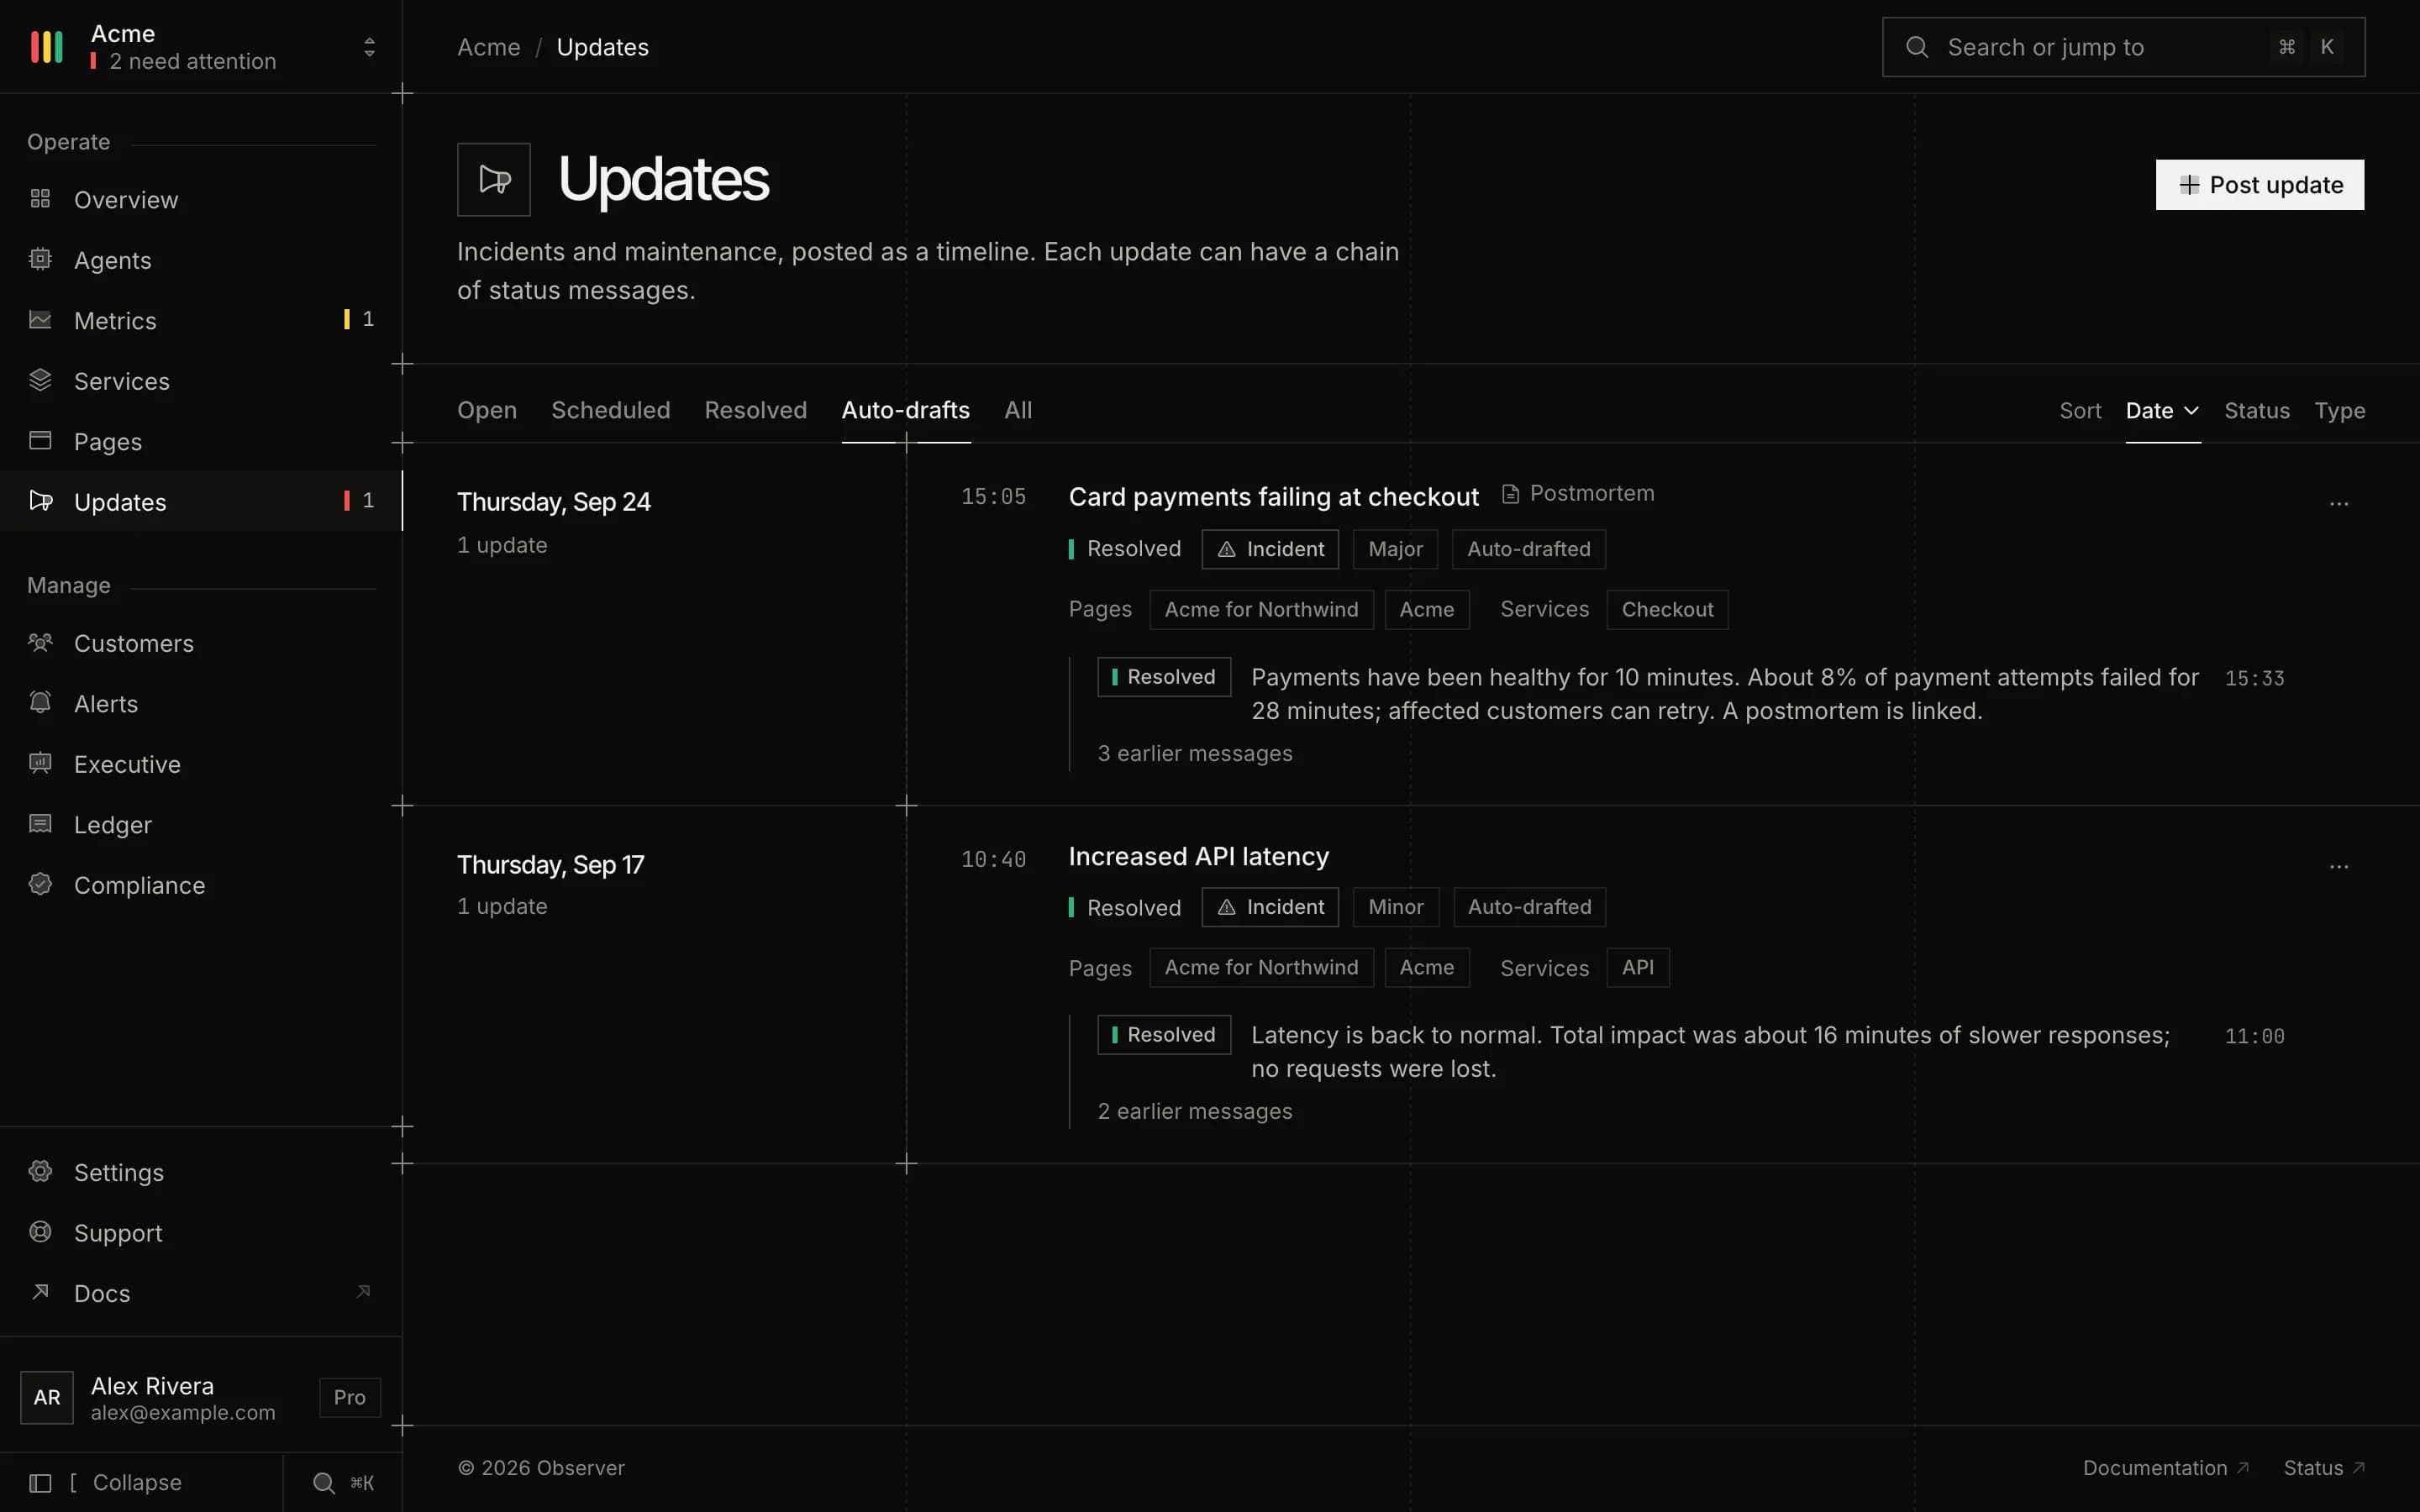
The Auto-drafts filter in the console: incidents a metric breach drafted and a person published.
Customers
The right customers, and only them.
An incident can be public, or scoped to the customers it affects. Targeting decides whose subscribers are emailed.
Visibility
Scoped to the customers it hits.
ProAttach an incident to customers and only their pages show it. Leave it unscoped and it is public.
Targeting
Choose who gets the email.
Notify no customers, selected customers or all of them, on top of your public subscribers. Each customer's subscribers can be left out.
Closing the loop
Everyone told gets the all clear.
Resolved goes to every subscriber who was emailed about the incident.
Maintenance
Planned work is not an outage.
Schedule the window once. It opens, closes and tells subscribers on its own.
Schedule
It runs itself.
A published window starts and completes on schedule, with a timeline message at each end.
Subscribers
Told before and after.
Emails when the window is scheduled, again within the hour before it starts, and when it completes or is canceled.
Alerts
Planned work does not page you.
Metric alerts for a page under a running window are held. A channel can opt back in. Recoveries always deliver.
Console / Updates / Maintenance
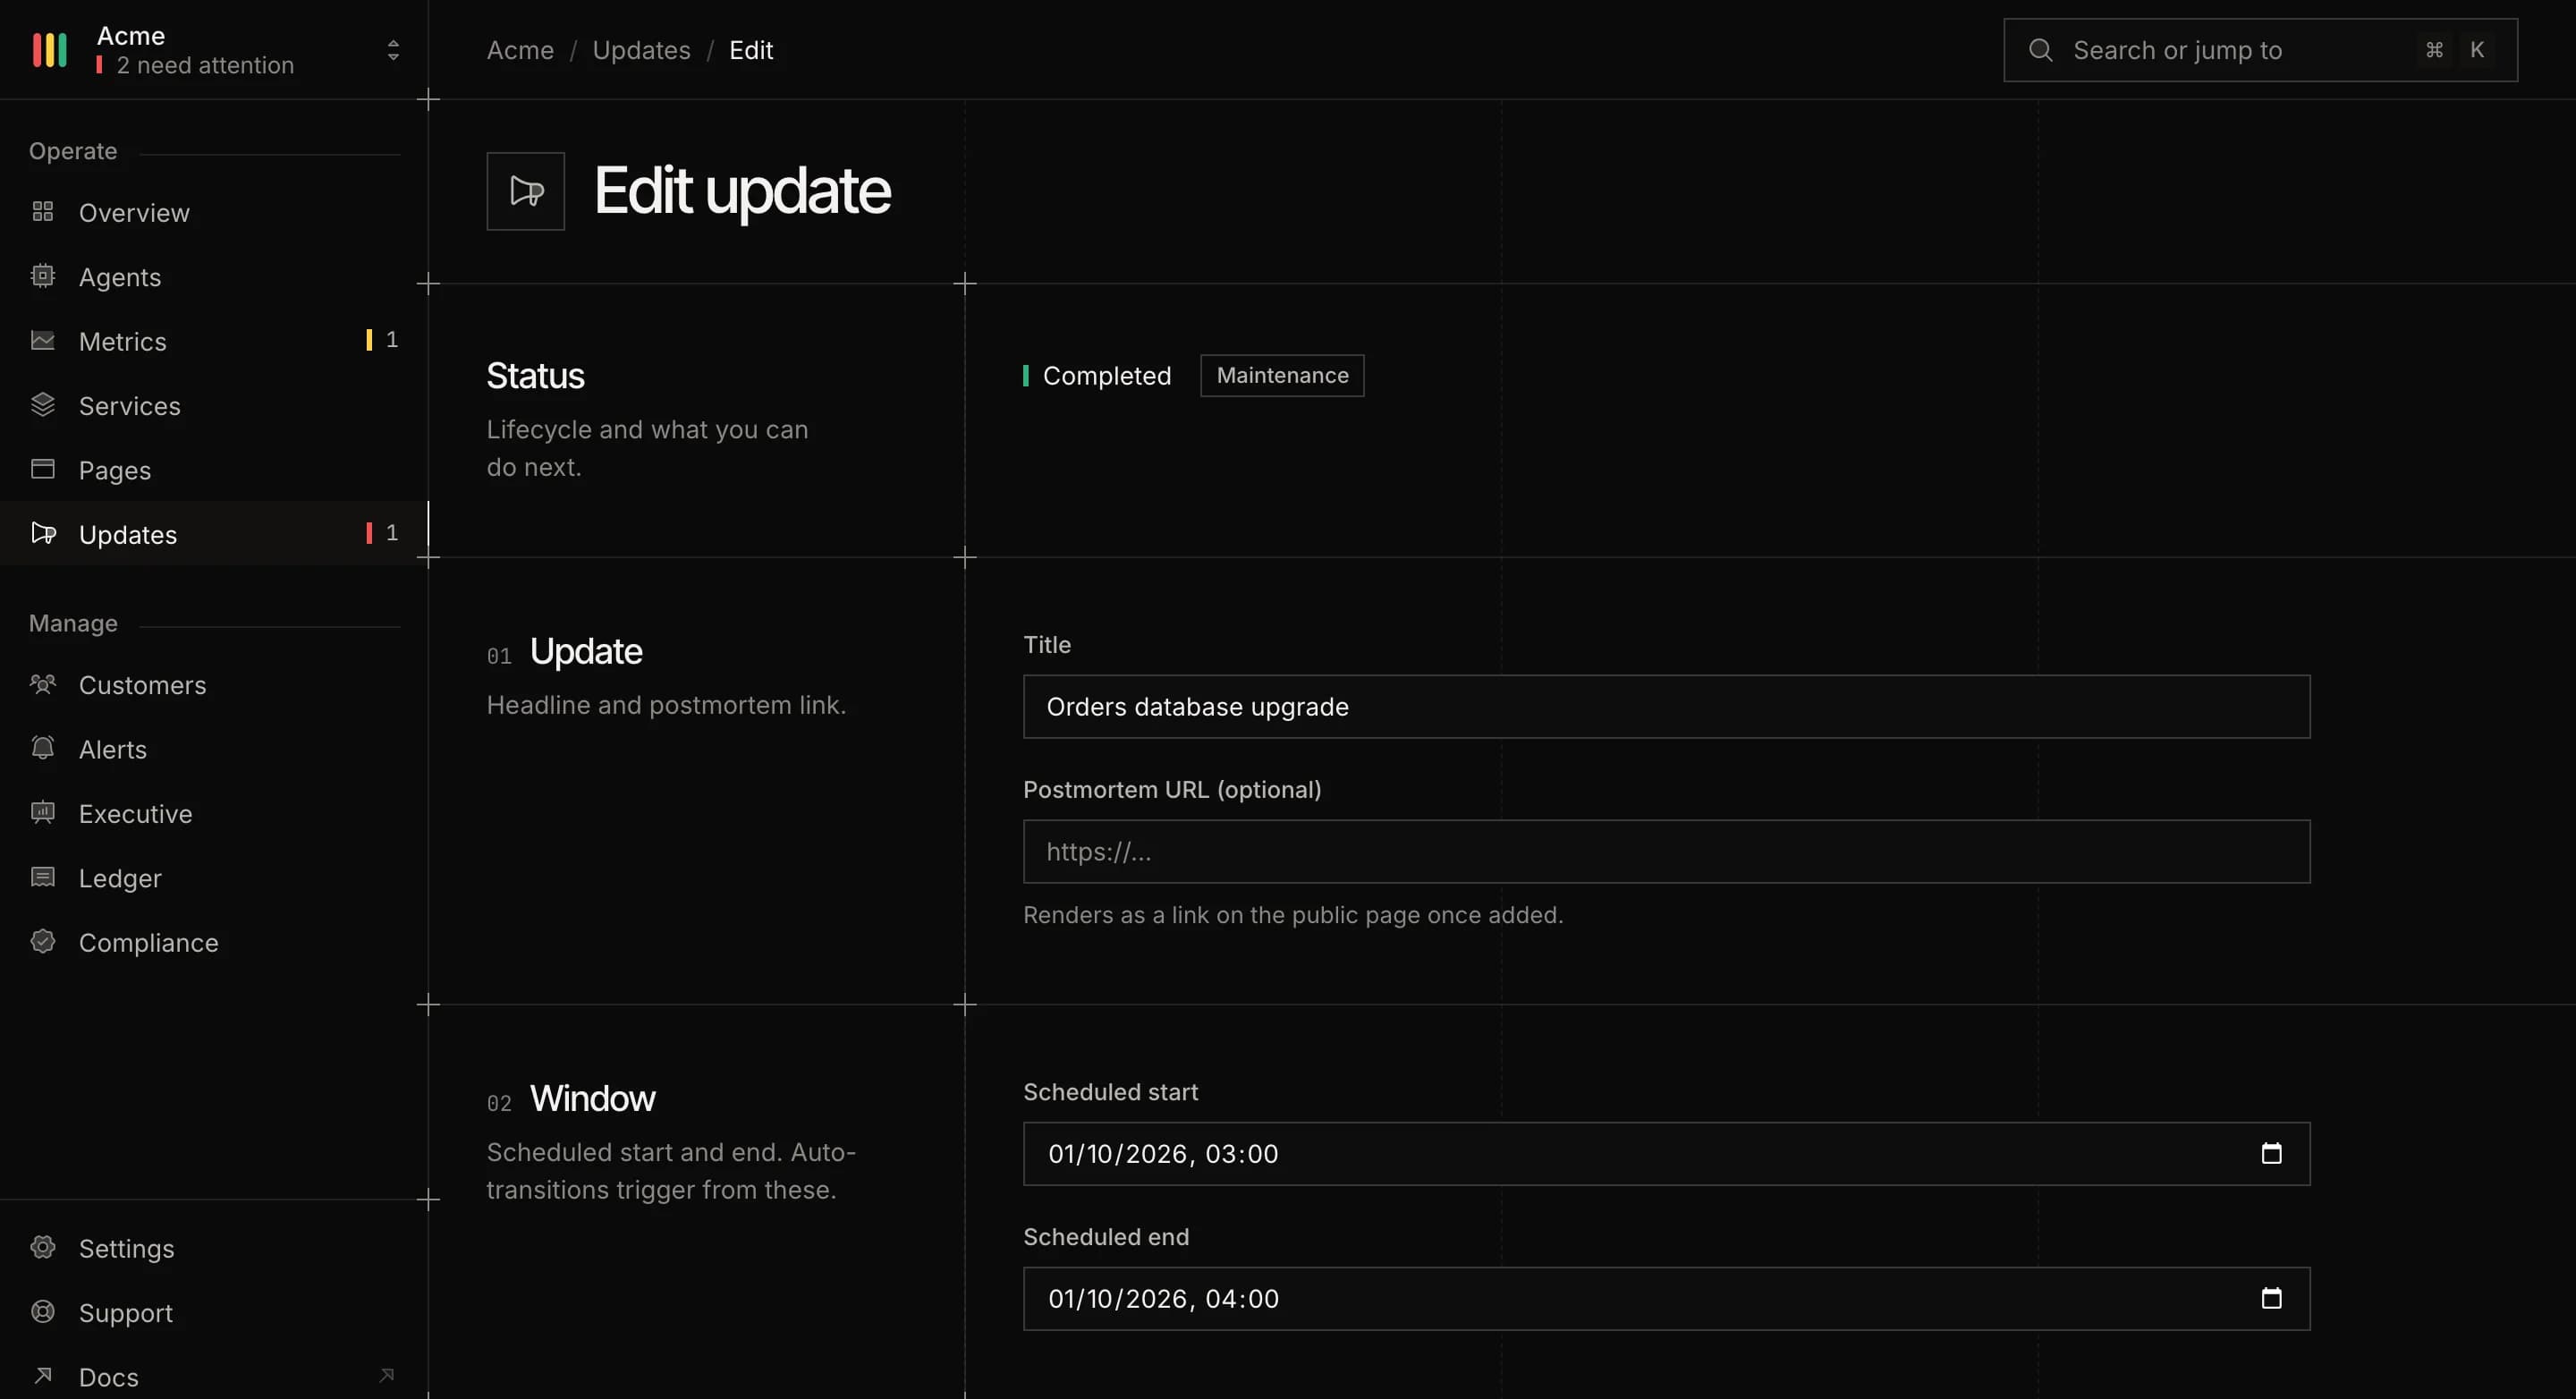
A completed maintenance in the console, with its scheduled window.
Afterwards
The record stays.
Postmortem
Link the write-up.
Add a postmortem link to any incident. The status page links it under the incident's timeline.
History
Every incident, on the record.
Published incidents stay on the page's incident history and its RSS and Atom feeds.
API and MCP
Post from your pipeline.
Open, update, publish and resolve incidents and maintenance over the REST API. The MCP server exposes the same operations as tools.
Open and publish
Response
Resolve with a message
Response
A Resolved message closes the incident.
MCP tools
One tool per operation.
API, Starter+Incident and maintenance tools are generated from the same OpenAPI spec, under your key's scopes.
- listIncidents
- createIncident
- publishIncident
- appendIncidentMessage
- resolveIncident
- draftIncidentFromMetric
- createMaintenance
- cancelMaintenance